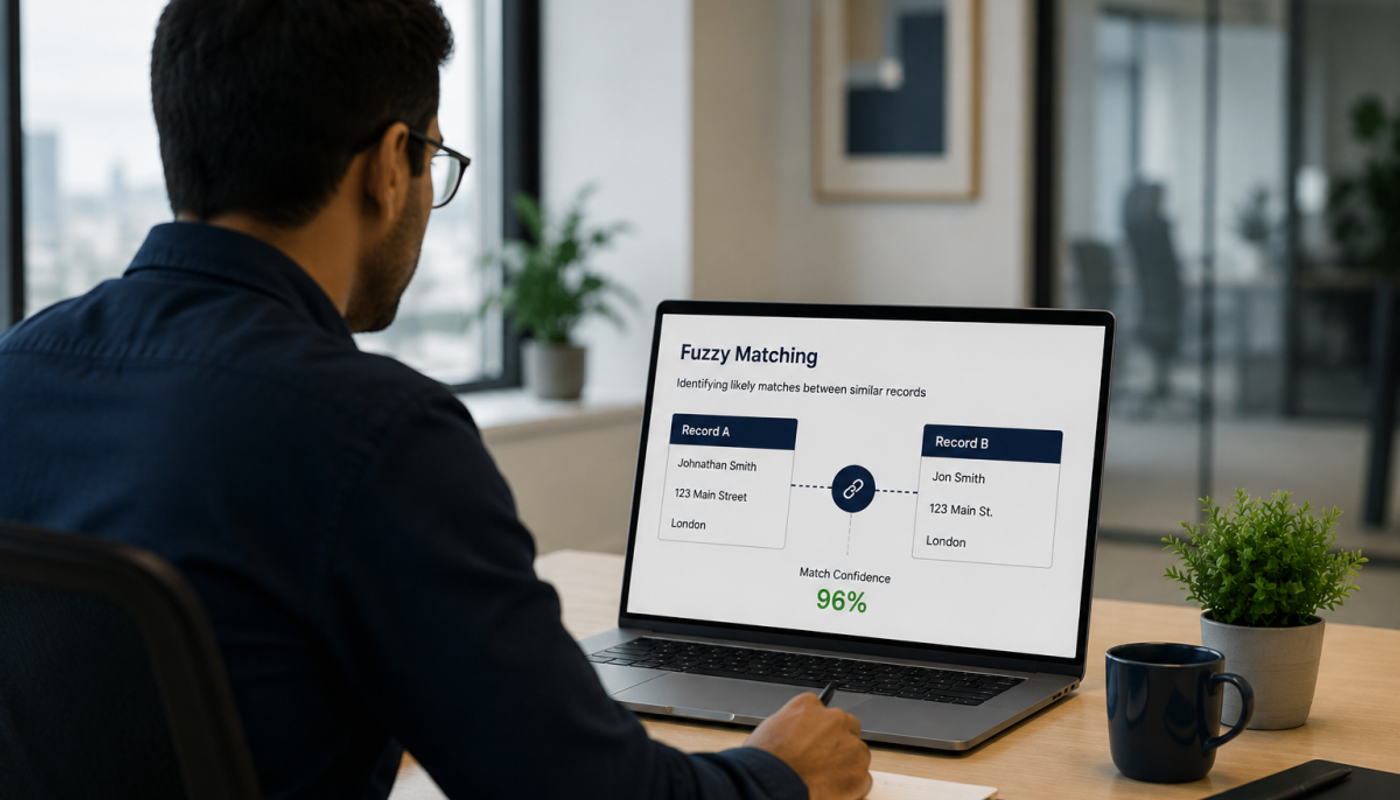
A name may appear in several forms across customer records and watchlists. Exact matching can miss genuine risks, while overly broad rules create irrelevant alerts. Fuzzy matching AML systems help identify meaningful variations without treating every similarity as a confirmed match.
AML screening false positives waste compliance time and delay onboarding. A screening alert indicates a possible match, not confirmed sanctions risk. Fuzzy matching combines name similarity with identifiers such as date of birth, nationality and location to help analysts prioritise credible matches and reduce false positives screening teams must investigate.
In this guide, you’ll learn how fuzzy matching works in AML screening, why false positives occur, how thresholds and contextual identifiers improve accuracy, and what to look for in a modern screening solution.
Binderr AML Screening Software for Smarter Matching
Modern AML screening software should identify meaningful name variations while using context to distinguish genuine risks from irrelevant matches. Binderr combines global risk screening, smart matching and broader risk-management capabilities.
Key capabilities include:
- Screen individuals and businesses against sanctions, PEPs and watchlists
- Check global adverse media sources
- Use AI-powered smart matching to reduce false positives
- Screen companies, directors, shareholders, UBOs and complex entities
- Apply Dynamic Risk Assessment using customer and screening data
- Monitor customers and connect AML Screening with KYC, KYB, CDD and EDD
What Is Fuzzy Matching in AML Screening?
Fuzzy matching is an AML screening technique that identifies similar, but not identical, names and customer data. It can detect variations exact matching may miss, such as Mohamed Rahman and Mohammed Rahman, including typos, aliases, transliteration and reversed name order. Fuzzy matching AML technology supports more flexible name matching AML workflows while helping reduce false positives screening teams encounter.
Used in sanctions, PEP, watchlist and adverse-media screening, it generates potential matches that still require review using details such as date of birth, nationality and address. OFAC’s Sanctions List Search uses edit-distance, Jaro-Winkler and Soundex matching alongside exact-name searches.
Run Your First AML Screen
Why Exact Name Matching Is Not Enough for AML Screening
Exact name matching can miss genuine sanctions, PEP and watchlist matches when customer records contain spelling, formatting or transliteration differences.
Fuzzy matching in AML screening helps identify these legitimate name variations while supporting more accurate false-positive reduction and helping reduce false positives screening teams would otherwise need to investigate manually.
Spelling variations
Names can vary legitimately across customer records, passports and sanctions lists. For example, Steven may appear as Stephen, while Mohamed may be recorded as Muhammad. Fuzzy matching helps identify these variations without relying on exact matches, improving screening accuracy and supporting better name matching AML outcomes while reducing unnecessary false positives.
Typographical errors
Simple data-entry mistakes can prevent exact matching from identifying a genuine customer or watchlist record. For example, Anderson might become Andersen, or Petrov might become Petorv.
AML fuzzy matching detects these minor differences and assigns a similarity score, helping teams investigate plausible matches without treating every spelling error as a new identity. When properly calibrated, this approach can reduce false positives screening analysts receive from weak or poorly ranked similarities.
Transliteration
Names written in Arabic, Cyrillic, Chinese or other scripts can have several valid Latin-script spellings. Fuzzy matching AML systems use transliteration, phonetic logic and name similarity to connect these variations, improving global sanctions and PEP screening.
Binderr identifies transliteration and spelling differences as key uses of fuzzy matching. This makes name matching AML particularly important for firms serving international customers.
Word order
Naming conventions differ across countries and databases, so the same person may appear as Li Wei in one record and Wei Li in another. Token-based fuzzy matching compares name components rather than their order, while additional identifiers such as date of birth or nationality help reduce irrelevant alerts and reduce false positives screening teams may otherwise need to review.
Initials and abbreviations
Customer and watchlist records may shorten names into initials or abbreviations. For example, Mohammed Abdullah Khan could appear as M. A. Khan. Fuzzy matching can compare name tokens and available identifiers to identify potential relationships without escalating every abbreviated record. Combining these signals supports more reliable name matching AML and helps reduce false positives screening caused by formatting differences.
Aliases and alternative names
Individuals and entities may appear under legal names, former names, trading names, aliases or alternative spellings. Alias-aware fuzzy matching helps compare these variations, while contextual data helps analysts distinguish genuine matches from false positives. A well-designed fuzzy matching AML process should therefore consider aliases as part of broader name matching AML rather than treating them as isolated records.
Prefixes, suffixes and titles
Titles and name elements such as Dr, Sheikh, Mr, Jr, bin, al-, de and van may appear differently across documents and watchlists. A robust fuzzy matching AML system should account for these variations.
The FCA's 2026 review identified this as good screening practice. Handling these elements consistently can also help reduce false positives screening teams encounter when records contain additional titles or name components.
Start AML Screening for Free
What Is a False Positive in AML Screening?
An AML screening false positive occurs when a system flags a customer or business as a potential match to a sanctions list, PEP database or watchlist, but investigation confirms they are unrelated. For example, John Michael Smith, born in 1991 in the UK, may resemble a sanctions record for John Smith, born in 1958 with a different nationality.
Conflicting identifiers suggest a false alert. As Wolfsberg guidance notes, an alert does not prove sanctions risk. Excessive false positives increase analyst workload, delay onboarding and raise compliance costs, making identifiers such as date of birth, nationality, address and ID numbers essential. These identifiers strengthen name matching AML decisions and help reduce false positives screening teams must resolve.
Why AML Screening Generates So Many False Positives
AML screening false positives occur when a system flags an unrelated customer as a potential match to a sanctions, PEP or watchlist record. Alert volume depends on data quality, screening thresholds, database coverage and available identifiers such as date of birth, nationality, address or company details. Effective fuzzy matching AML configuration can help reduce false positives screening teams face, but only when the underlying data and rules are reliable.
Common names - Names such as John Smith or Maria Garcia may match many unrelated people, increasing false-positive alerts. Name frequency, geography and customer risk should be considered alongside similarity scores to improve name matching AML decisions.
Incomplete customer data - Screening only a first and last name makes it harder to distinguish individuals. Full legal names, dates of birth, nationality, addresses and identification details provide stronger evidence and help reduce false positives screening teams receive from name-only comparisons.
Poor data quality - Misspellings, inconsistent formatting, duplicate records and missing or outdated information can reduce screening accuracy, creating false positives or causing genuine matches to be missed. Normalisation and reliable fuzzy matching AML processes can help address some of these issues, but they cannot replace accurate customer data.
Overly sensitive thresholds - Thresholds set too low may flag weak similarities. While this can improve recall, it may also create alert backlogs and increase manual review costs. Threshold calibration is therefore central to both fuzzy matching AML performance and efforts to reduce false positives screening teams must handle.
Inadequate contextual matching - Name similarity alone rarely proves a match. Comparing dates of birth, nationality, residence, occupation and other identifiers helps distinguish genuine matches from false positives. This contextual approach makes name matching AML more useful because it evaluates whether similar records are likely to represent the same person or entity.
Weak transliteration rules - Names from Arabic, Cyrillic, Chinese and other scripts may have several valid Latin spellings. Poor transliteration and phonetic matching can cause missed matches or unnecessary alerts. Fuzzy matching AML systems should support these variations while using contextual data to reduce false positives screening teams encounter.
Large and overlapping databases - Sanctions, PEP, adverse-media and commercial watchlists may contain duplicate entries, aliases or overlapping profiles. Without deduplication and alert prioritisation, one customer may trigger multiple alerts for the same potential match. Combining name matching AML with record consolidation and risk-based prioritisation can help reduce false positives screening teams investigate repeatedly.
Simplify the AML Screening Process With Binderr
Fuzzy matching is one part of AML screening. Binderr connects potential matches with customer data, risk assessment and due diligence to help teams make faster, more informed decisions.
- Screen customers against sanctions, PEPs, watchlists and adverse media.
- Detect spelling, alias and transliteration variations with smart matching.
- Review matches with customer, company and ownership data.
- Assess risk with Dynamic Risk Assessment.
- Trigger CDD or EDD for higher-risk customers.
- Monitor changes in sanctions, PEP and adverse media status.
How Does Fuzzy Matching Work?
Fuzzy matching in AML screening compares names and customer data to identify meaningful similarities, even when spelling, formatting, word order or transliteration differs.
By combining name normalisation, similarity scores and supporting identifiers, it helps compliance teams detect potential matches, improve name matching AML processes and reduce unnecessary AML screening false positives. When properly configured, it can also help reduce false positives screening teams face during sanctions, PEP and watchlist reviews.
Data Normalisation
Before AML screening begins, data normalisation standardises customer and watchlist names by converting text to lowercase, removing punctuation and titles, standardising spacing, processing accents and separating name components.
For example, Dr. MOHAMMED AL-HASSAN could become mohammed al hassan, helping fuzzy matching focus on meaningful differences rather than formatting. This initial step supports more consistent name matching AML results and gives screening systems a cleaner foundation for identifying relevant similarities.
Edit Distance
Levenshtein distance measures the character changes needed to turn one name into another. It helps AML screening software detect minor spelling differences, such as Andersen and Anderson, without requiring an exact match.
However, thresholds must be carefully calibrated to avoid increasing false positives and unnecessary reviews. Used appropriately, edit-distance analysis can help reduce false positives screening teams encounter by distinguishing minor, meaningful variations from weaker similarities.
Jaro-Winkler Similarity
Jaro-Winkler similarity compares strings based on matching characters, their positions and whether they appear near the beginning of a name. It helps identify minor spelling differences and rank stronger matches above weaker ones.
OFAC includes Jaro-Winkler in its sanctions-list search methodology, showing how it can support fuzzy matching AML workflows beyond exact-name screening. By ranking results rather than treating every similarity equally, this approach can support more focused investigations and improve name matching AML accuracy.
Phonetic Matching
Phonetic matching identifies names that sound alike despite different spellings, such as Steven and Stephen. Algorithms like Soundex can help detect variations caused by different languages, pronunciations or data-entry errors. OFAC combines Soundex with other similarity techniques, but additional identifiers are still needed to distinguish genuine matches from false positives.
Combining phonetic analysis with other controls can help reduce false positives screening teams receive from superficial name similarities while preserving sensitivity to genuine variations.
Transliteration Matching
Transliteration matching helps AML screening systems compare names written in different scripts or represented in Latin characters through multiple accepted spellings. By combining transliteration rules with fuzzy matching, software can recognise international name variations, improve screening coverage and avoid treating every similar name as a confirmed match.
This is an important part of fuzzy matching AML because international customers may have several legitimate representations of the same name. It also strengthens name matching AML processes across multilingual customer populations.
Token and Name-Order Matching
Token matching evaluates individual name parts rather than the complete character sequence. It can recognise that Carlos Miguel Fernandez and Fernandez Carlos Miguel may represent the same person, while also accounting for missing middle names, prefixes, suffixes and compound surnames. This makes it useful for international AML screening.
Because it evaluates the structure of a name rather than only its exact character order, token matching can improve name matching AML outcomes and help reduce false positives screening teams caused by formatting or ordering differences.
Similarity Scores
A similarity score, often shown on a 0–100 scale, indicates how closely a customer record resembles a sanctions, PEP or watchlist entry. A higher score suggests greater similarity but does not confirm a match. Thresholds should be calibrated and documented based on factors such as risk appetite, screening type, jurisdiction, customer data and regulatory expectations.
Similarity scores are central to fuzzy matching AML because they allow firms to rank potential matches and apply proportionate review rules. They should support, rather than replace, contextual analysis and analyst judgement.
So, How Can Fuzzy Matching Reduce False Positives?
Traditional AML screening may treat every similar name the same. Intelligent similarity scoring creates a more nuanced assessment by considering spelling, name order, aliases, transliteration and phonetic similarity. This helps compliance teams distinguish likely sanctions or PEP matches from weak similarities, reducing false positives without relying on exact matching alone.
In practice, fuzzy matching AML works best when it is combined with reliable customer information and risk-based rules. This broader approach can help reduce false positives screening teams face while maintaining the ability to identify meaningful name variations.
Contextual information filters weak matches
Name similarity is only the starting point in an AML investigation. Screening software can compare details such as date of birth, nationality, address and passport number to determine whether a customer matches a watchlist subject.
Significant differences may indicate a false positive. As BIS explains, combining fuzzy matching with corroborating information helps firms assess potential sanctions matches more accurately.
This additional context is also essential for effective name matching AML because similar names alone do not establish that two records belong to the same person.
Example:
Identifier | Customer | Watchlist profile | Result |
Name | Mohammed Hassan | Mohamed Hassan | Similar |
Date of birth | 1992 | 1961 | Different |
Country | UK | Syria | Different |
Passport | Different | Different | Different |
Overall result | Likely false positive |
Common names receive less weight
Name rarity can improve AML screening precision. An exact match for a common name such as “John Smith” may be less meaningful than one for a rare name, since many unrelated people may share it. Modern screening systems can weigh name frequency alongside date of birth, nationality, geography, aliases and other identifiers, helping reduce false positives without overlooking distinctive matches.
This type of contextual weighting makes fuzzy matching AML more precise and supports better name matching AML decisions when common names generate multiple potential alerts.
Better ranking prioritises meaningful alerts
Effective fuzzy matching does more than generate alerts; it ranks potential matches by relevance and confidence. High-confidence matches can be prioritised for analyst review, while low-confidence matches may be suppressed or deprioritised under documented policies. This helps compliance teams focus on the most plausible sanctions, PEP and watchlist matches, reducing backlogs and improving screening efficiency.
Prioritised alert handling is one way to reduce false positives screening teams must investigate manually, provided suppression and escalation rules are documented, tested and regularly reviewed.
Why More Fuzziness Does Not Always Mean Better Screening
More fuzziness does not automatically mean better AML screening. If rules are too strict and rely on exact matching, firms may generate fewer alerts but miss genuine sanctions, PEP or watchlist matches caused by spelling variations, aliases or transliteration.
A balanced approach uses calibrated fuzzy matching to capture relevant name variations while keeping alert volumes manageable. By contrast, overly permissive fuzzy matching can create a large pool of weak similarities, increasing AML false positives, analyst workload and investigation costs.
The FCA has warned that screening configured too narrowly may miss potential matches, while rules set too broadly can produce excessive false positives. The goal is not maximum fuzziness; it is the right balance between recall and precision.
For this reason, fuzzy matching AML should be treated as a configurable screening capability rather than a universal solution. The most effective name matching AML programmes combine similarity analysis with identifiers, risk context and human review to reduce false positives screening teams without weakening detection.
Combine Smart AML Matching With Dynamic Risk Assessment Using Binderr
Finding a potential AML match is only the first step. Binderr’s Dynamic Risk Assessment combines KYC, KYB and AML data to calculate the customer’s risk level.
Binderr Can Help Compliance Teams:
- Screen customers against sanctions, PEPs and watchlists
- Run adverse media checks
- Use smart matching to improve screening relevance
- Combine screening results with KYC and KYB information
- Analyse company directors, shareholders and UBOs
- Automatically calculate risk scores and trigger EDD when risk increases
Threshold Calibration: The Key to False Positive Reduction
Fuzzy-matching thresholds determine how similar two names must be before an AML system creates a potential match. Calibration is as important as the algorithm: thresholds should be tested against real customer data and historical alerts to balance detection accuracy with manageable investigation volumes.
Careful calibration is essential to fuzzy matching AML because the same score may have different significance across customer populations, jurisdictions and name structures. It is also a core requirement for effective name matching AML and sustainable efforts to reduce false positives screening teams.
Threshold too low - A low threshold catches more spelling variations, aliases, transliterations and phonetic similarities. However, it can also generate excessive weak matches, increasing false positives, alert backlogs and onboarding delays.
Threshold too high - A high threshold produces fewer alerts but may miss misspelled, abbreviated, transliterated or reordered names, increasing the risk of false negatives.
Properly calibrated threshold - The right threshold balances precision and recall based on the organisation’s risk appetite, customer base, jurisdictions and data quality. There is no universal score; thresholds should be tested, documented and reviewed after material changes to systems, watchlists or screening rules.
Organisations should monitor both alert volumes and outcomes to determine whether their fuzzy matching AML configuration is identifying meaningful matches. Reviewing cleared alerts, escalations and missed-match testing can show whether name matching AML rules are helping reduce false positives screening teams without creating unacceptable false-negative risk.
Reduce False Positives with Binderr
Key Best Practices for Fuzzy Matching
Use these AML screening best practices to improve fuzzy name matching, reduce false positives in screening and identify genuine sanctions, PEP and watchlist matches more effectively.
A well-calibrated approach to fuzzy matching AML combines name normalisation, transliteration, phonetic matching, contextual identifiers and regular threshold testing to support accurate, risk-based screening.
Use fuzzy rather than exact-only screening where appropriate - Fuzzy matching in AML screening helps identify legitimate name variations, typographical errors and transliteration differences that exact matching may miss. Configure name matching AML controls according to your risk appetite so they improve detection without creating unnecessary AML false positives.
Account for aliases and alternative spellings - Sanctions, PEP and watchlist records may include aliases, former names or different spellings of the same person or entity. Including these variations in AML name screening helps identify potential matches more reliably while giving analysts better context for clearing irrelevant alerts and reducing false positives in screening.
Support multiple scripts and transliteration - Names originally written in Arabic, Cyrillic, Chinese or other scripts can have several valid Latin-script representations. Screening software should support transliteration and non-Latin name matching to reduce the risk of missed sanctions or PEP matches in international customer populations.
Combine character and phonetic similarity - Edit-distance methods can identify spelling differences, while phonetic matching can detect names that sound alike but are written differently. Using both approaches can improve fuzzy matching AML accuracy and help compliance teams distinguish meaningful similarities from weak matches.
Use dates of birth, nationality and other identifiers - Name similarity alone is rarely enough to confirm a match. Comparing dates of birth, nationality, address, passport details and company information helps separate genuine matches from false positives, supports name matching AML decisions and enables more efficient alert investigation.
Test screening after meaningful configuration changes - Validate AML screening performance after changing match thresholds, algorithms, data sources or watchlists. Regular testing helps confirm that the system still detects relevant name variations, supports efforts to reduce false positives in screening and meets the organisation’s risk-based compliance requirements.
Can Fuzzy Matching Eliminate AML False Positives?
No. Fuzzy matching cannot eliminate AML false positives because unrelated individuals or businesses may share similar names, dates of birth, locations or other identifying details.
Its purpose is to improve AML screening accuracy by recognising spelling variations, aliases, transliterations and phonetic similarities while using contextual data to filter out weak matches. Properly calibrated fuzzy matching AML controls can reduce unnecessary sanctions-screening and PEP-screening alerts, but they should not be treated as a zero-alert solution or a replacement for analyst review.
The realistic goal is to reduce false positives in screening and limit irrelevant investigations without materially weakening the detection of genuine financial-crime risk.
Move From AML Screening to End-to-End Compliance With Binderr
Fuzzy matching is only one part of AML screening. Binderr connects KYC, risk assessment, onboarding decisions and ongoing monitoring in one compliance platform.
- Verify individuals with AI-powered KYC, document and biometric checks.
- Verify businesses, directors, shareholders and UBOs globally.
- Screen against sanctions, PEPs, watchlists and adverse media.
- Use smart matching to reduce false positives.
- Combine KYC, KYB and AML data into risk scores.
- Continue with CDD, EDD and ongoing monitoring.
Bottom Line
Exact name matching is too rigid for modern AML screening. Properly calibrated fuzzy matching can identify plausible matches despite spelling, transliteration, alias and data-entry differences.
However, it works best alongside contextual identifiers, risk-based thresholds, regular testing and analyst review. This balanced approach improves name matching AML accuracy, reduces unnecessary alerts and helps compliance teams focus on genuine financial-crime risk.
Binderr Services helps businesses streamline compliance screening, risk assessment and ongoing monitoring in one connected workflow.